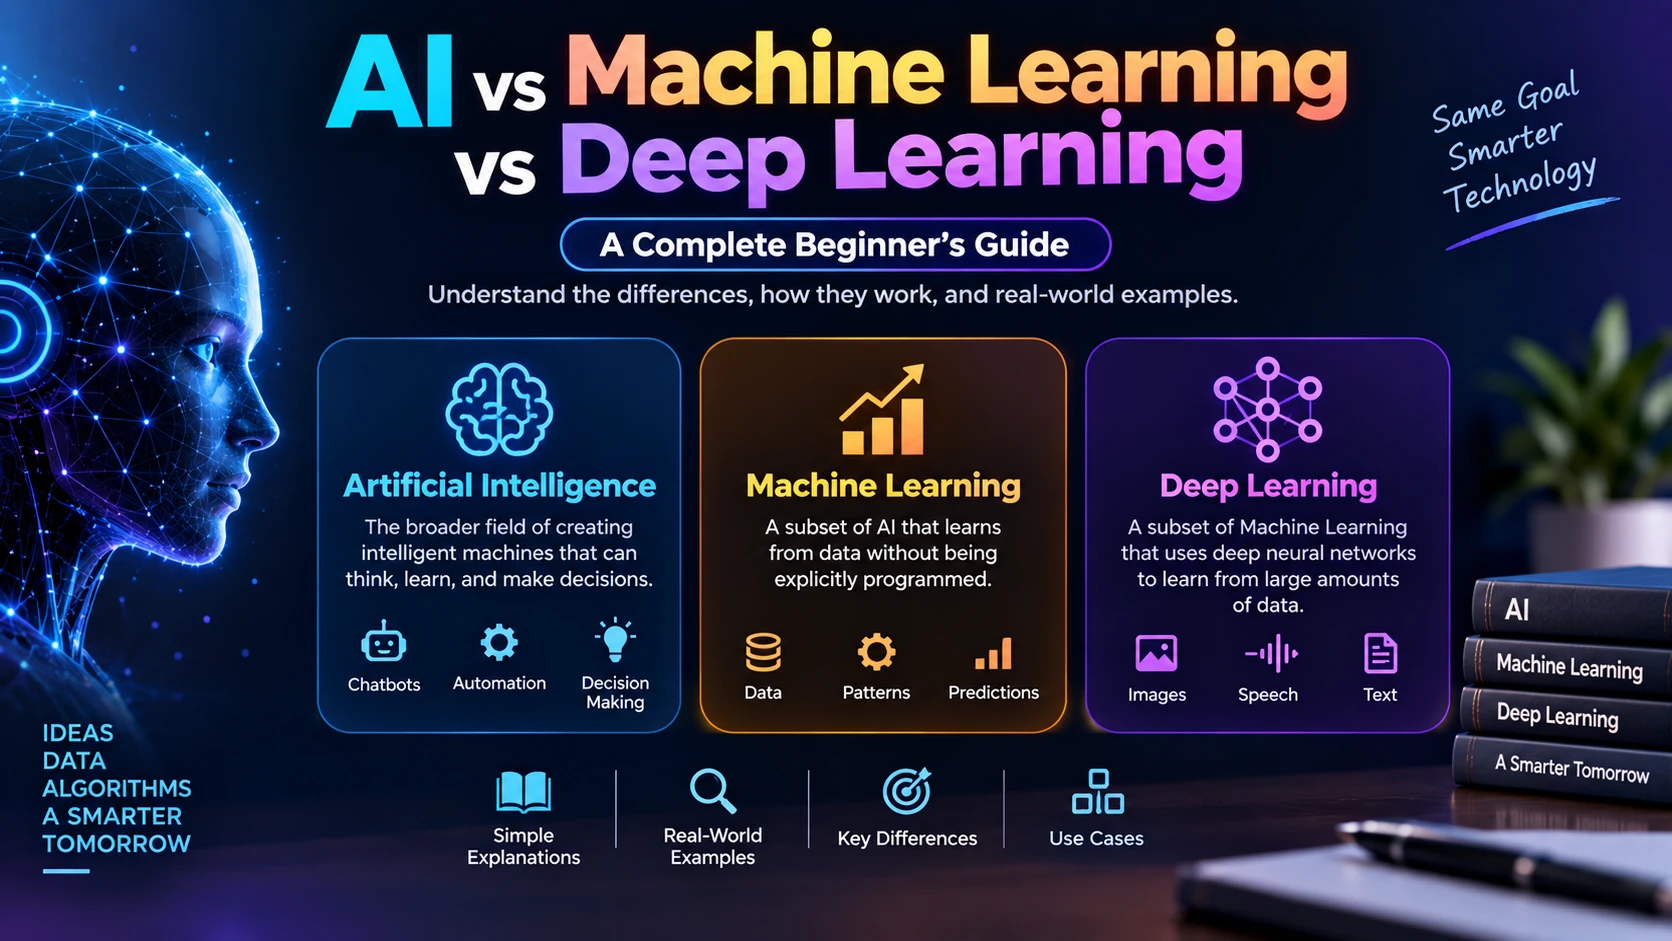
Artificial Intelligence, Machine Learning, and Deep Learning are closely related terms, but they do not mean the same thing. Beginners often see these terms used together and assume they are interchangeable. They are not. A simple way to understand the relationship is: Machine Learning is a subset of Artificial Intelligence, and Deep Learning is a […]
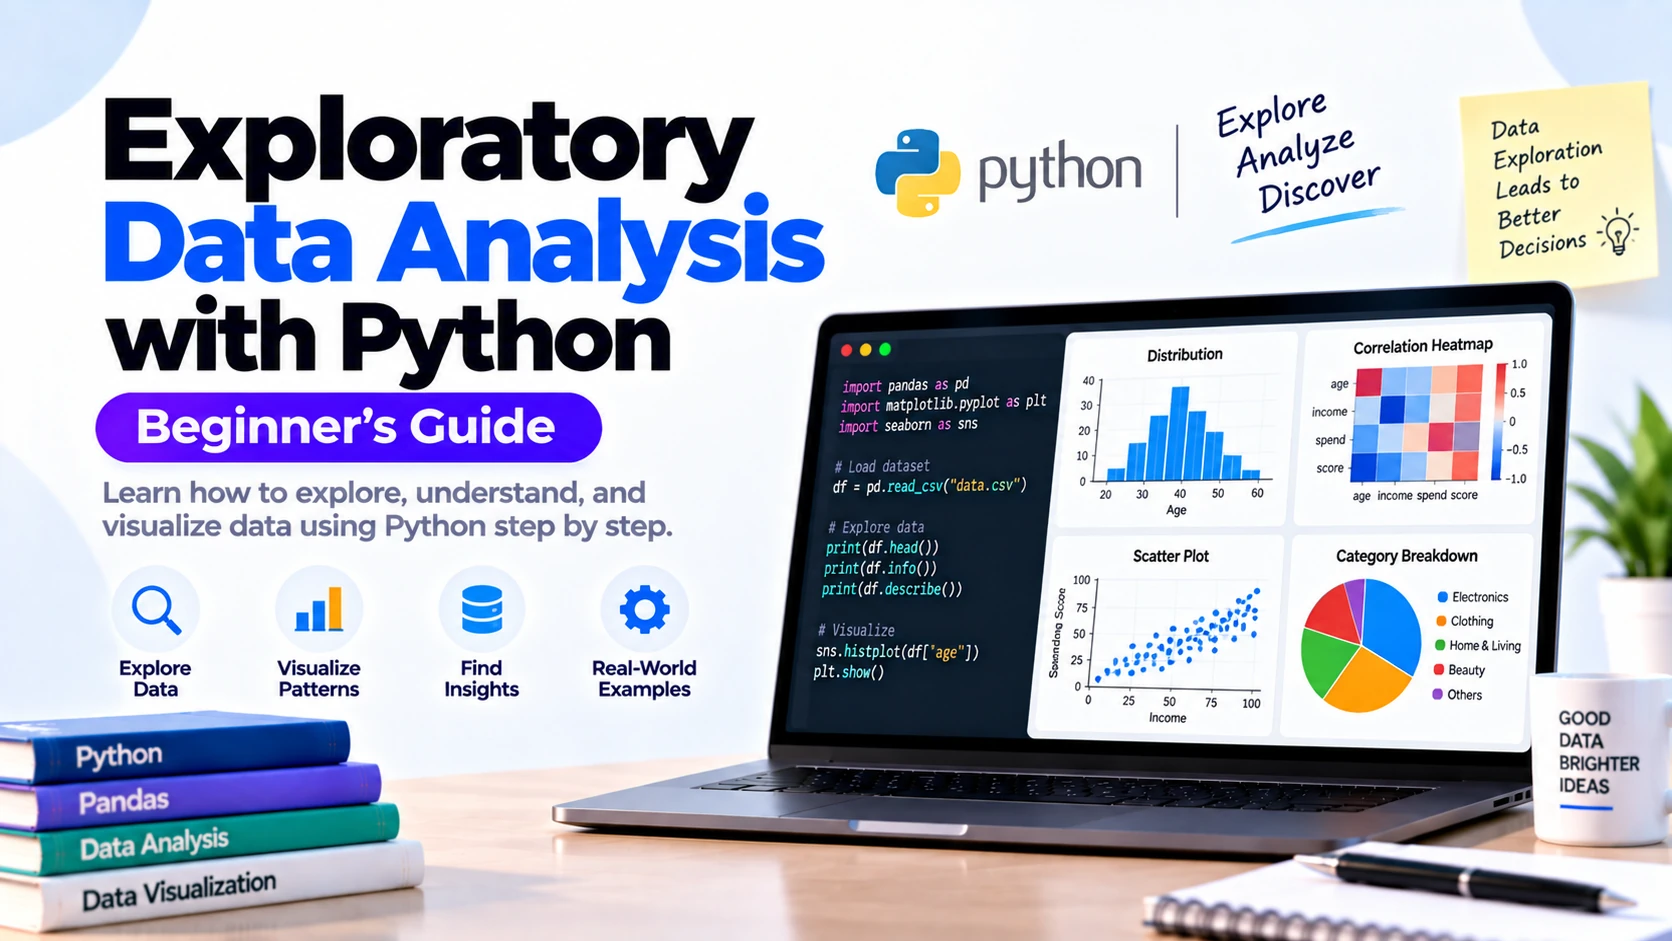
Exploratory Data Analysis, commonly called EDA, is the process of examining, cleaning, summarizing, and visualizing a dataset before building machine learning models or making important conclusions. When you receive a new dataset, you usually do not know everything about it. You may not know: EDA helps answer these questions. For example, suppose you receive a […]
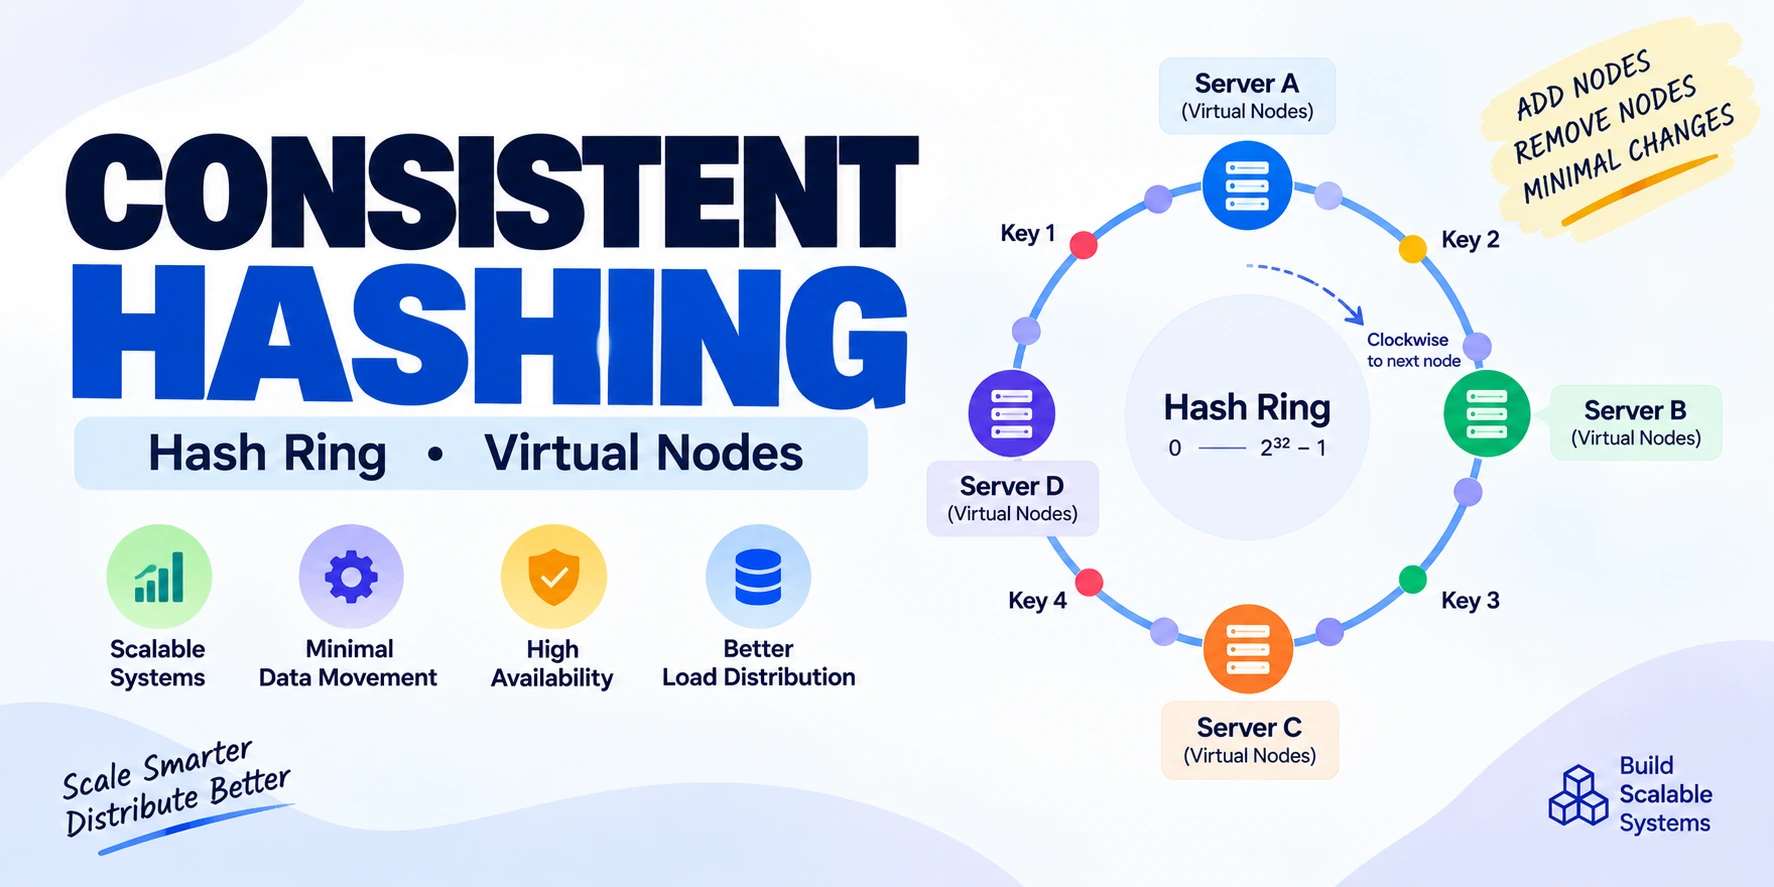
When a distributed system grows, data often needs to be distributed across multiple servers. For example, imagine an application with millions of users. Storing all user data on a single server may create performance, scalability, and availability problems. Instead, the system can distribute data across multiple servers. But this creates an important question: How does […]
Data visualization is the process of turning raw data into charts, graphs, and other visual forms that make information easier to understand. When working with Python, you may have hundreds or thousands of rows containing numbers, categories, dates, and measurements. Reading those values directly from a table can make patterns difficult to recognize. A visualization […]
Matplotlib is one of the most popular Python libraries for creating charts and data visualizations. If you are learning Python for data science, machine learning, or AI development, Matplotlib is an important library to learn after NumPy and Pandas because it helps you understand data visually. For example, suppose you have monthly sales data: You […]
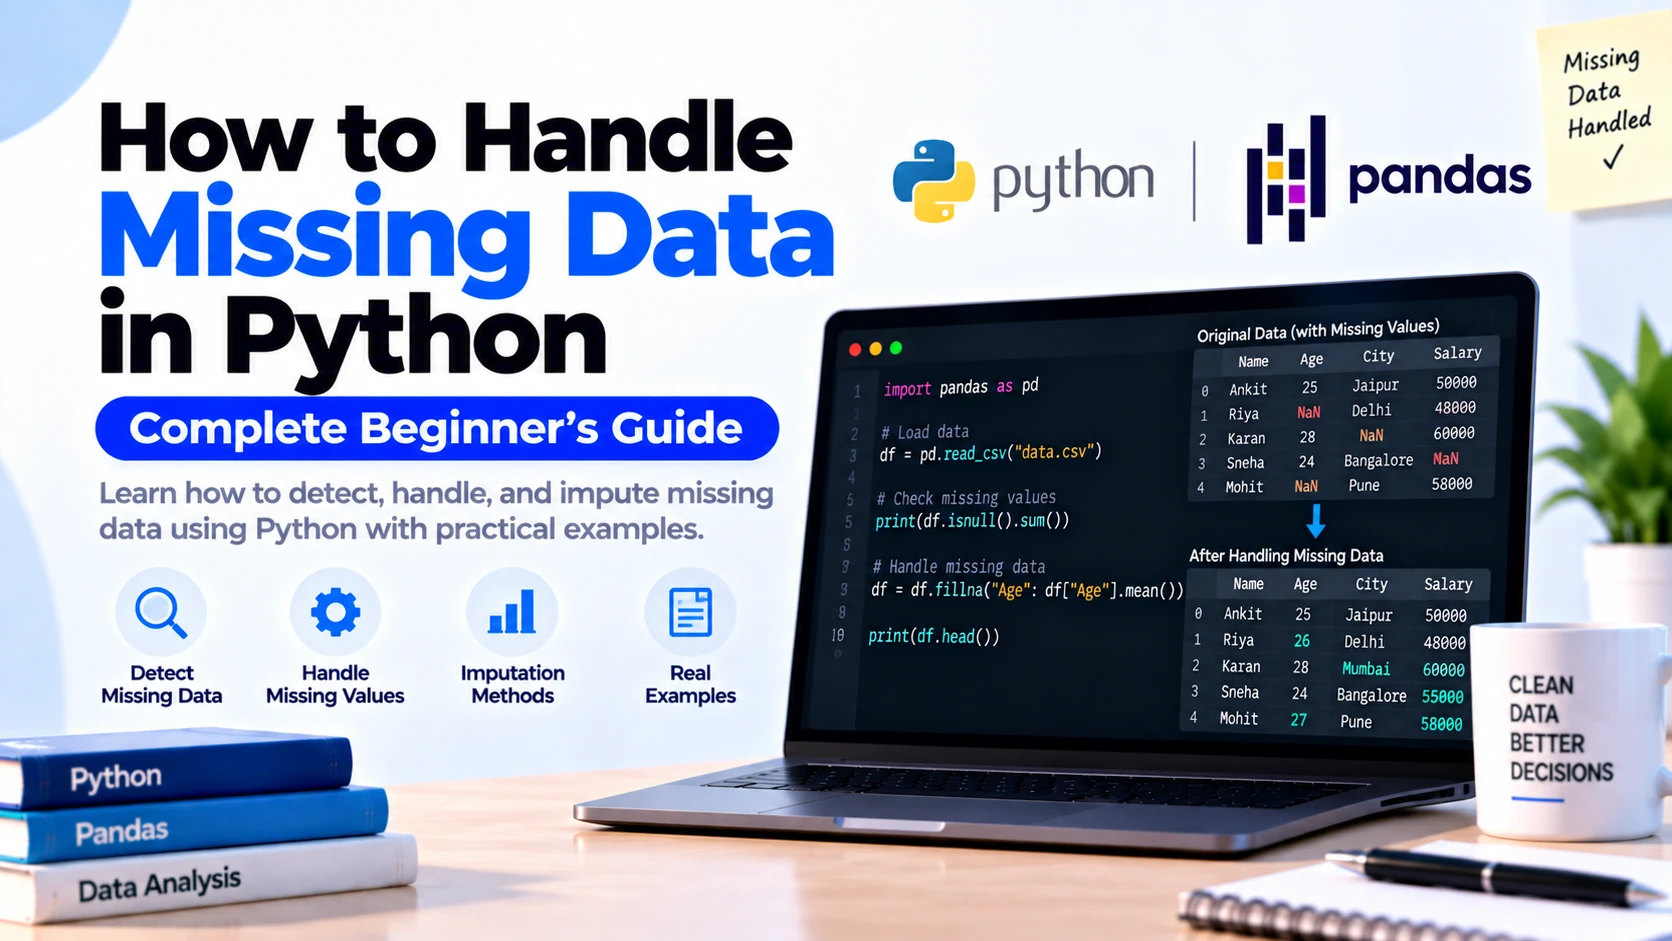
Missing data is one of the most common problems you will face when working with real-world datasets in Python. A dataset may contain empty cells, None, NaN, blank strings, “unknown”, “N/A”, or other values that represent missing information. For example: Before analyzing this data or using it for machine learning, you need to decide how […]
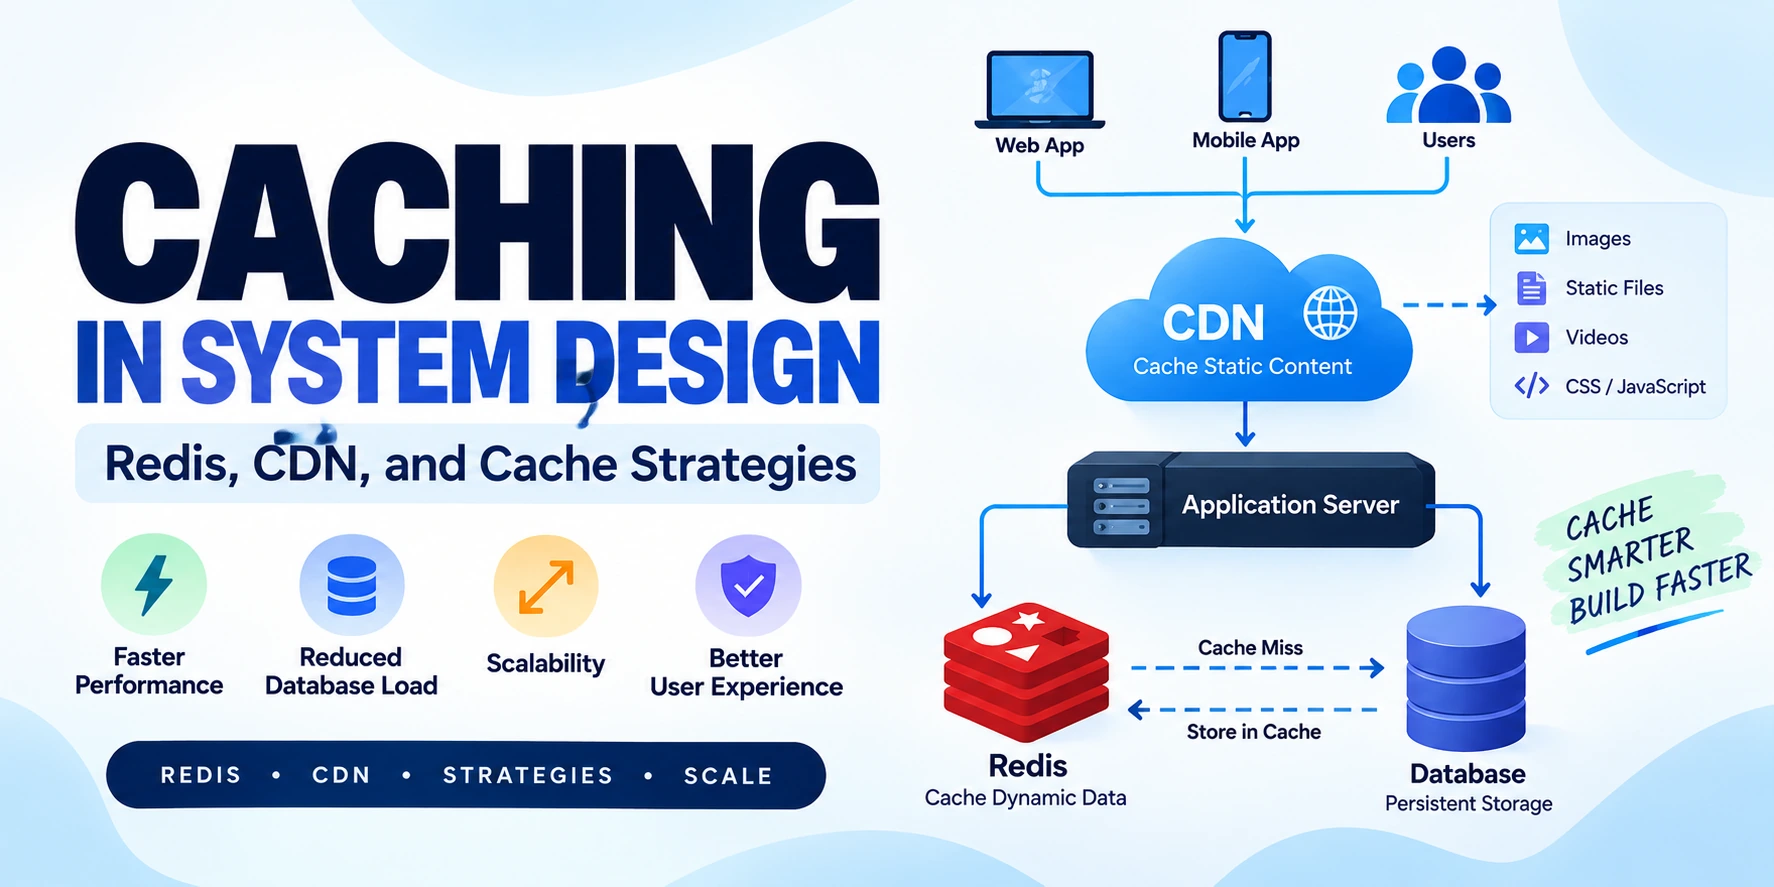
Modern applications are expected to respond quickly, even when they serve thousands or millions of users. However, repeatedly fetching the same data from databases, APIs, or remote servers can increase latency and put unnecessary pressure on backend infrastructure. This is where caching becomes an important part of system design. Caching stores frequently accessed or expensive-to-compute […]
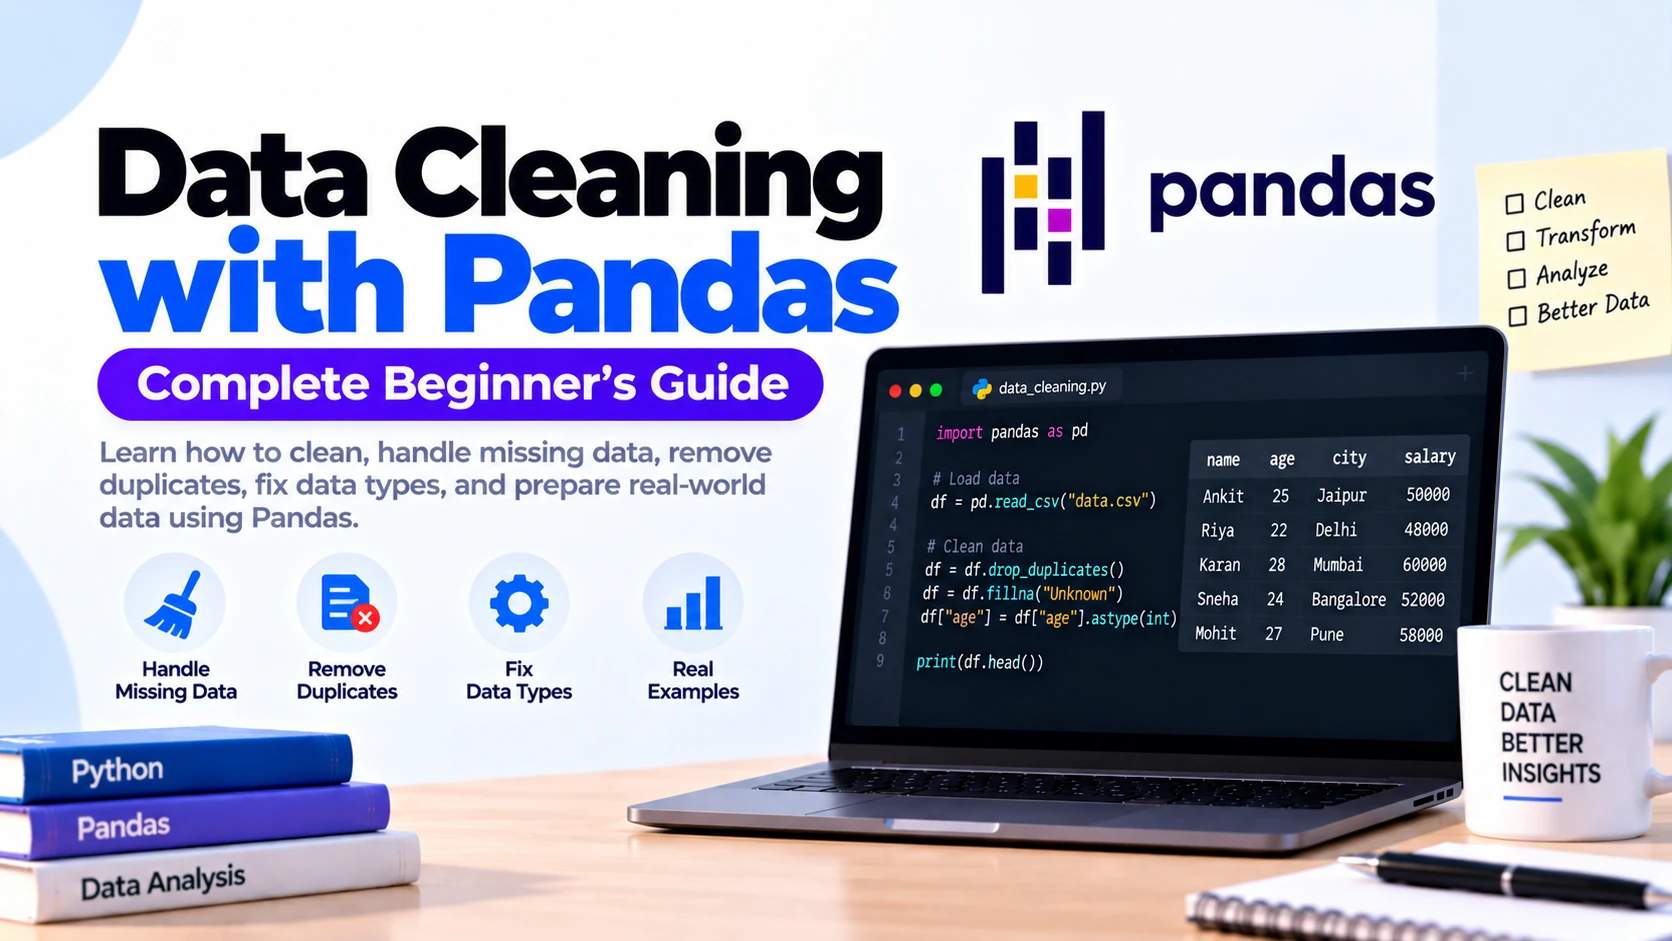
Data cleaning is the process of finding and fixing problems in a dataset before you analyze it or use it for machine learning. Real-world data is rarely perfect. A CSV or Excel file may contain missing values, duplicate rows, incorrect data types, inconsistent text, invalid numbers, extra spaces, unusual date formats, or unnecessary columns. Pandas […]
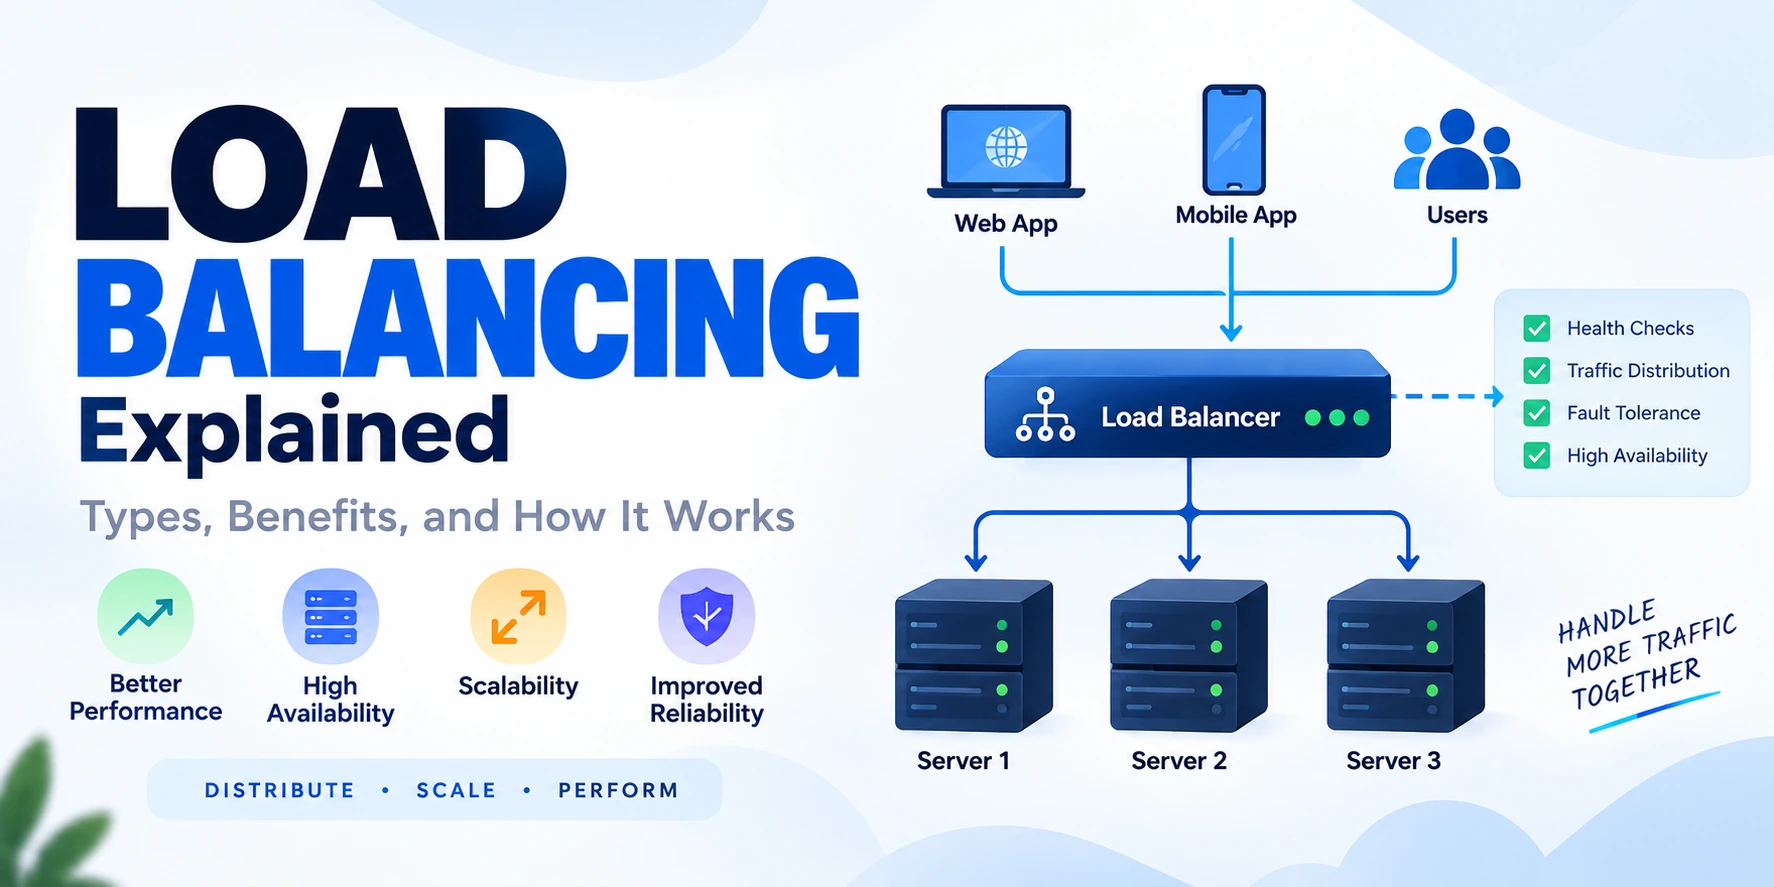
Modern websites and applications can receive thousands or even millions of requests from users. If all of those requests are handled by a single server, the server can become overloaded, slow, or unavailable. This is where load balancing becomes important. Load balancing distributes incoming traffic across multiple servers so that no single server has to […]
Page 141 of 203